Troubleshooting High CPU Issues
When dealing with high CPU or memory
consumption on a controller, it is crucial to collect and analyze specific information
before reaching out to RUCKUS
Support. Controllers experiencing these issues may exhibit various symptoms that you
need to
document thoroughly for the promptest resolution.
- Complete the following verification and validations to ensure the appropriate data
is collected:
- Determine when the issue first appeared (date and time). This can help correlate the onset of the problem with any other events, changes, or issues occurring at the same time.
- Check for alarms on the vSZ controller or the virtual machine (VM). These alarms can provide insights into resource depletion or similar problems.
- Note the number of APs and switches connected to the controller. Monitoring the controller's capacity versus the current network devices managed, including APs and switches, is essential. Controllers exceeding their capacity may encounter CPU and memory issues.
- If operating in a multi-node cluster environment, note the different network device capacity management. If you notice all the APs and switches are managed by one node only, this could be an indication of failure on specific nodes.
- Verify the CPU and RAM allocated to the VM via the hypervisor. Ensure the resource allocation aligns with the requirements.
- If multiple VMs are running on the same server, ensure system resources are not shared between VMs. Dedicate fixed resources to each specific VM.
- Run the following commands through the controller CLI and collect their output along with snapshot logs when the issue is occurring:
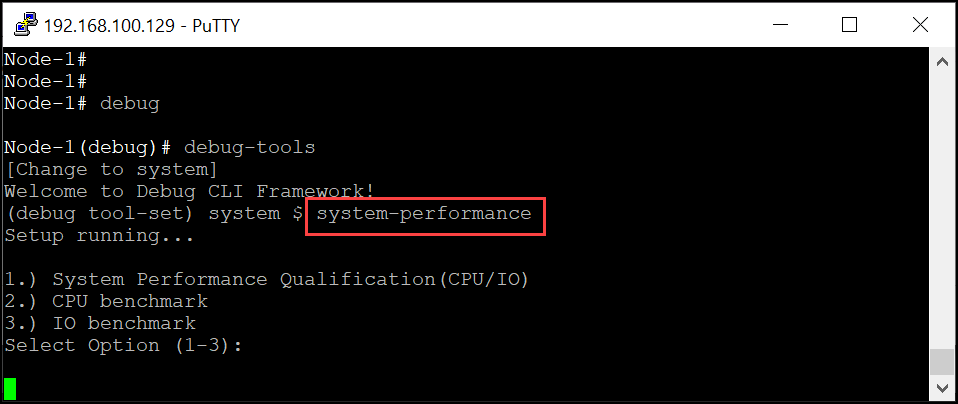
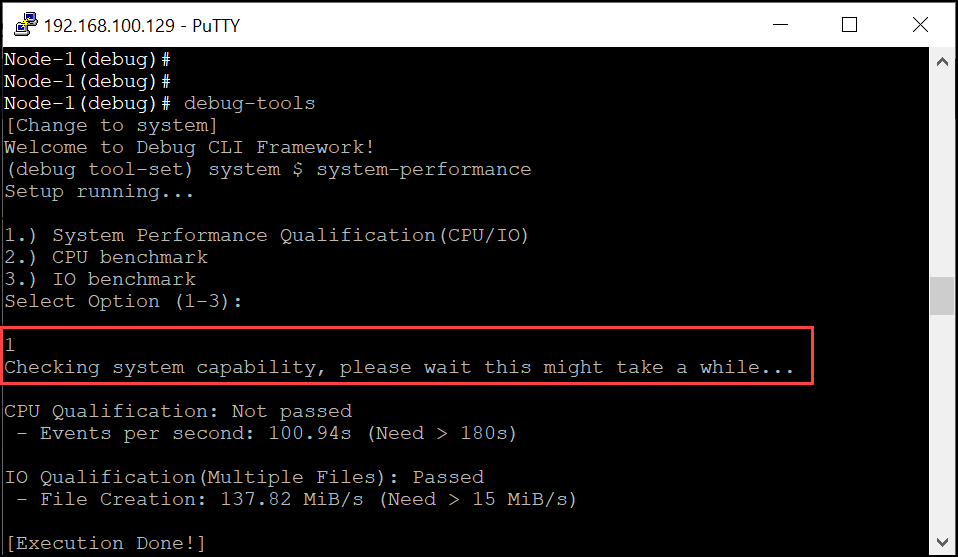
- To initiate thorough system performance debugging, you can employ the built-in tools within the controller. These tools are effective for conducting CPU and IO tests, which are crucial for pinpointing the source of CPU issues.
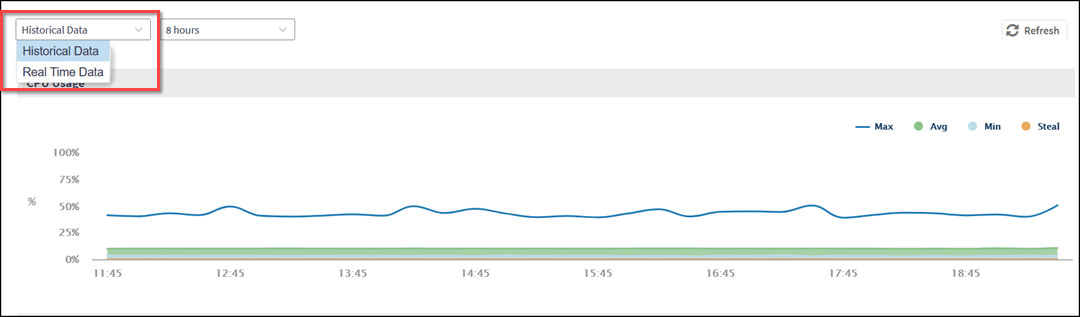
- Collect real-time resource
consumption data while the problem is present or collect historical data for trend
analysis during the day, week, or month.
- In the controller web GUI, select Network > Data and Control Plane > Cluster. The Cluster page opens.
- Select the node to monitor and scroll to select the Traffic & Health tab.
Note: Collect both real-time and historical data to help you identify trends and patterns that may indicate issues related to the time of the day, recurring load spikes, or seasonal usage behaviors, allowing for more targeted and effective troubleshooting.