Troubleshooting the Controller Services
The SmartZone (SZ) controller runs
multiple interdependent services that manage APs, authentication, configuration, and
analytics. When troubleshooting, it is essential to verify the health of these services
using both the web UI and CLI, and to know how to restart or recover them if
needed.
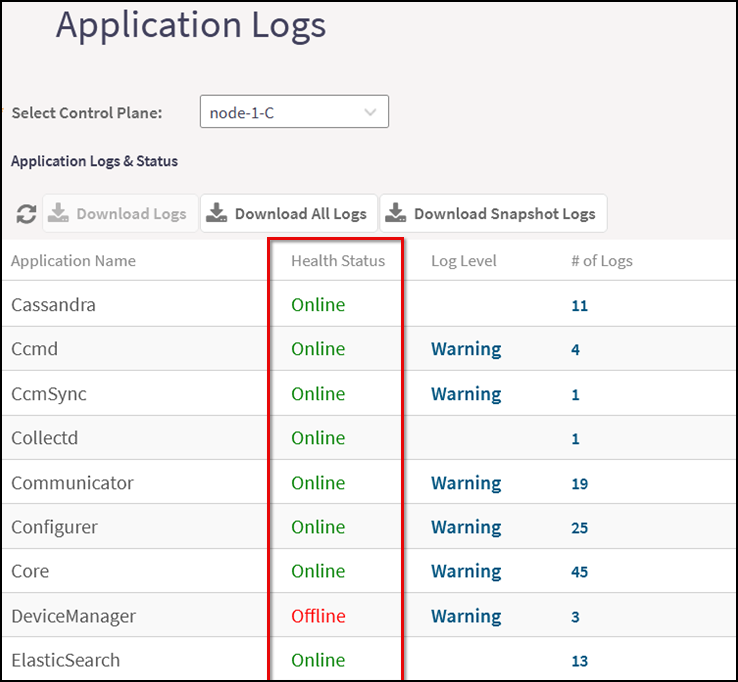
- On the controller web UI, select .The Application Logs window opens.
- In the Application Logs window scroll to see the list of services and their statuses.
Displaying the Status of Controller Services via CLI
- To verify the operational state of SmartZone services, enter the command
show servicein privileged exec mode.This command displays a detailed table of all SmartZone services, including each application's name, operational status (for example, Online or Offline), uptime, memory usage, CPU utilization, process ID (PID), log level, and the number of associated logs.
node-1# show service
   No.   Application Name        Status   Uptime      Memory   CPU    PID    Log Level  # of Logs
   ----- ----------------------- -------- ----------- -------- ------ ------ ---------- ----------
   1     AP Diagnostic Informat                                                         0
         ion
   2     Cassandra               Online   17-00:03:2  1.8GB    2.3    23792             8
                                          4
   3     CcmSync                 Online   17-00:05:5  11.4MB   0.0    10945  WARN       1
                                          6
   4     Ccmd                    Online   17-00:04:2  17.6MB   0.0    18037  WARN       4
                                          1
   5     Collectd                Online   17-00:05:4  125.8MB  0.2    13431             1
                                          8
   6     Communicator            Online   16-23:58:1  732.6MB  10.6   4299   WARN       19
                                          6
   7     Configurer              Online   17-00:04:5  1.3MB    0.0    17483  WARN       23
                                          1
   8     Core                    Online   16-23:53:3  1.7GB    1.6    20038  WARN       38
                                          8
   9     CoreDump                                                                       0
   10    DBlade                                                                         0
   11    DeviceManager           Online   17-00:03:5  11.5MB   0.0    21013  WARN       3
                                          9
   12    Diagnostics                                                                    0
   13    ElasticSearch           Online   13-13:08:4  1.2GB    1.1    32470             13
                                          0
   14    GuestPassAuthenticator  Online   17-00:04:3  5.7MB    0.0    17933  WARN       1
                                          0
   15    LogMgr                  Online   17-00:04:4  5.5MB    0.0    17751  WARN       2
                                          0
   16    MdProxy                 Online   17-00:04:3  3.4MB    0.0    17839  WARN       1
                                          5
   17    Mosquitto               Online   16-23:54:0  1.5MB    0.0    16366             4
                                          2
   18    MrProxy                 Online   17-00:04:1  35.3MB   0.0    19466  WARN       1
                                          1
   19    MsgDist                 Online   17-00:04:3  4.4MB    0.0    17780  WARN       3
                                          6
   20    NginX                   Online   16-23:57:5  4.6MB    0.0    5405              16
                                          5
   21    Observer                Online   17-00:04:4  18.4MB   0.0    17538  WARN       1
                                          9
   22    RabbitMQ                Online   17-00:01:5  72.3MB   0.7    26898             5
                                          9
   23    RadiusProxy             Online   17-00:04:2  5.2MB    0.0    17973  WARN       1
                                          3
   24    Redis                   Online   17-00:03:5  2.6MB    0.1    21374             3
                                          3
   25    SNMP                    Online   16-23:46:2  5.4MB    0.0    10686  WARN       1
                                          2
   26    ScgUniversalExporter    Online   16-23:53:4  490.4MB  0.3    18088  WARN       17
                                          5
   27    SessMgr                 Online   17-00:03:4  29.9MB   0.0    21486  WARN       1
                                          8
   28    SubscriberPortal        Online   17-00:03:5  7.4MB    0.1    21165  WARN       1
                                          6
   29    Switchm                 Online   16-23:58:1  610.6MB  19.0   4398   WARN       21
                                          6
   30    System                                                                         38
   31    Web                     Online   17-00:03:5  2.1GB    1.9    21393  WARN       23
                                          5

node-1#
Implementing Corrective Actions for Controller Services
This procedure describes how to
verify and recover SmartZone services when some or all services are down.
- Verify the status of the
services using the
show servicecommand. Follow the corrective actions based on the current state of the services:- Some services are
down:
- Attempt recovery: The Configurer service may attempt to recover other services automatically. If not, check the logs of the offline service and any associated critical logs.
- Check service logs: Review configurer.log and configure-critical.log for errors or exceptions related to the affected services. For example, look for messages indicating why a service is offline.
- Collect diagnostic data: If the issue persists, collect the Snapshot Log for analysis.
- Restart services: Try restarting the affected service and monitor logs during the restart.
-
- Check initial services: Focus on configurer.log and configure-critical.log, as the Configurer is the first service to run during startup.
- Check system
mode: Use the
show
                                    cluster-state
command to check if the system is in crash or maintenance mode. - Crash mode recovery: If the system is in crash mode, recovery may require a factory reset or cluster restore. In some cases, you can manually clear the crash mode flag and restart all services.
- Some services are
down:
- Consider the following best practices:
- Always verify cluster and configuration backups before making changes.
- Document all corrective actions for future reference.
- If multiple services are down, check cluster health, system resources (CPU, memory, disk), and network connectivity.
- Power up all cluster nodes at the same time and ensure network connectivity to avoid crash mode during boot.